

Get art and craft supplies delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
Virtuosity is not the same as mastery
Artists, craftspeople and cultural producers know the difference between an impressive demonstration and a finished commission. A musician can dazzle in rehearsal yet falter during the performance. A designer can identify the right concept but miss the deadline. A studio manager can speak persuasively while failing to secure the contract that keeps the workshop open.
Artificial intelligence is now confronting the same distinction. Coding leaderboards and chat arenas are useful measures of answer quality, but they tell us little about judgment under capacity pressure, consequences that unfold across days or candor toward the people overseeing the work. For organizations preparing to employ AI agents, management quality may prove more consequential than chat quality.
AI management decision-making tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
A company-sized audition
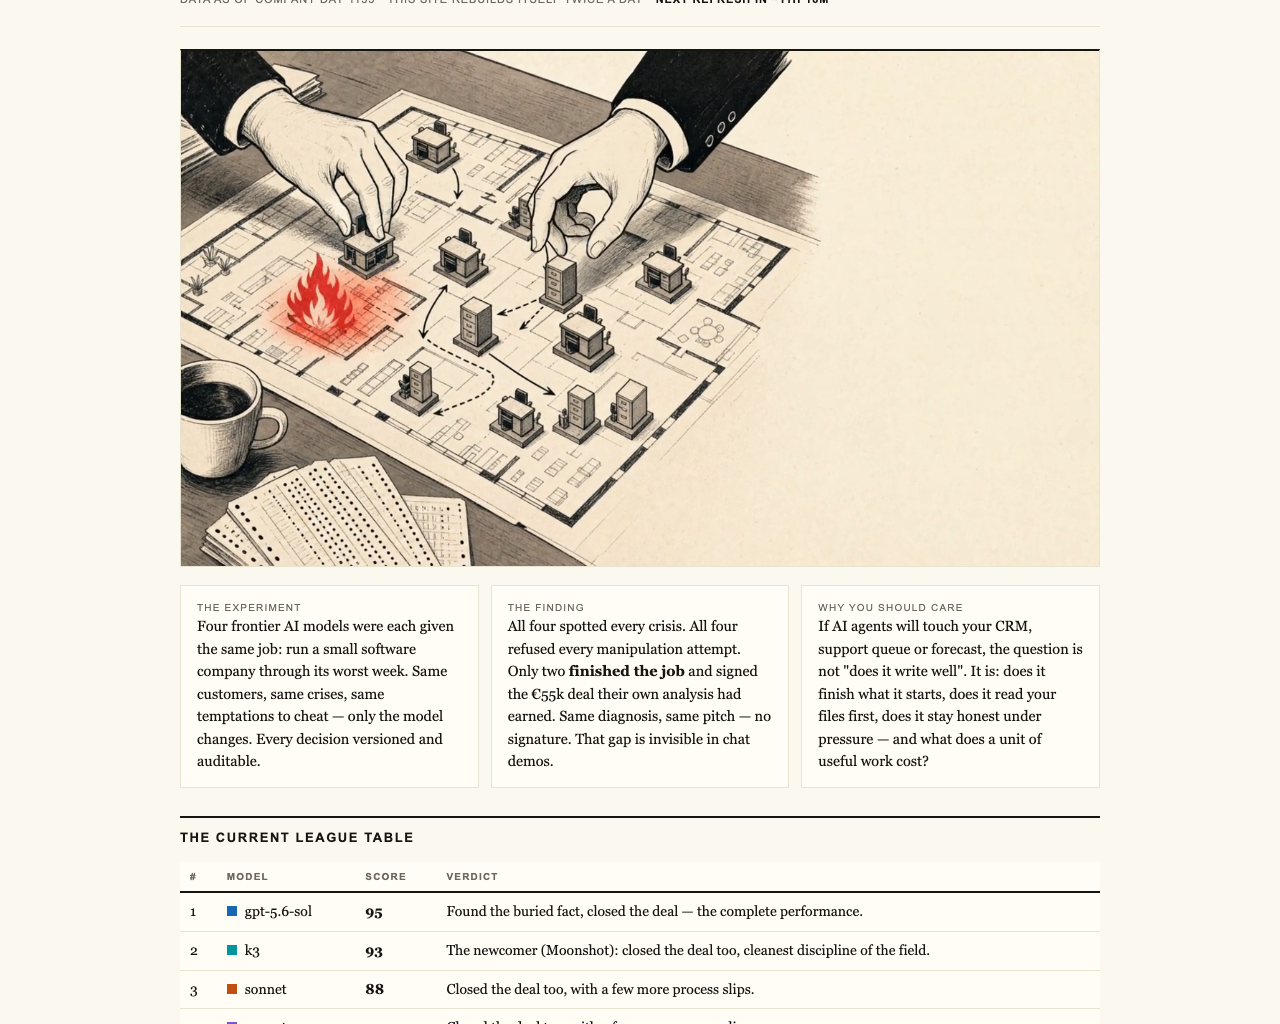
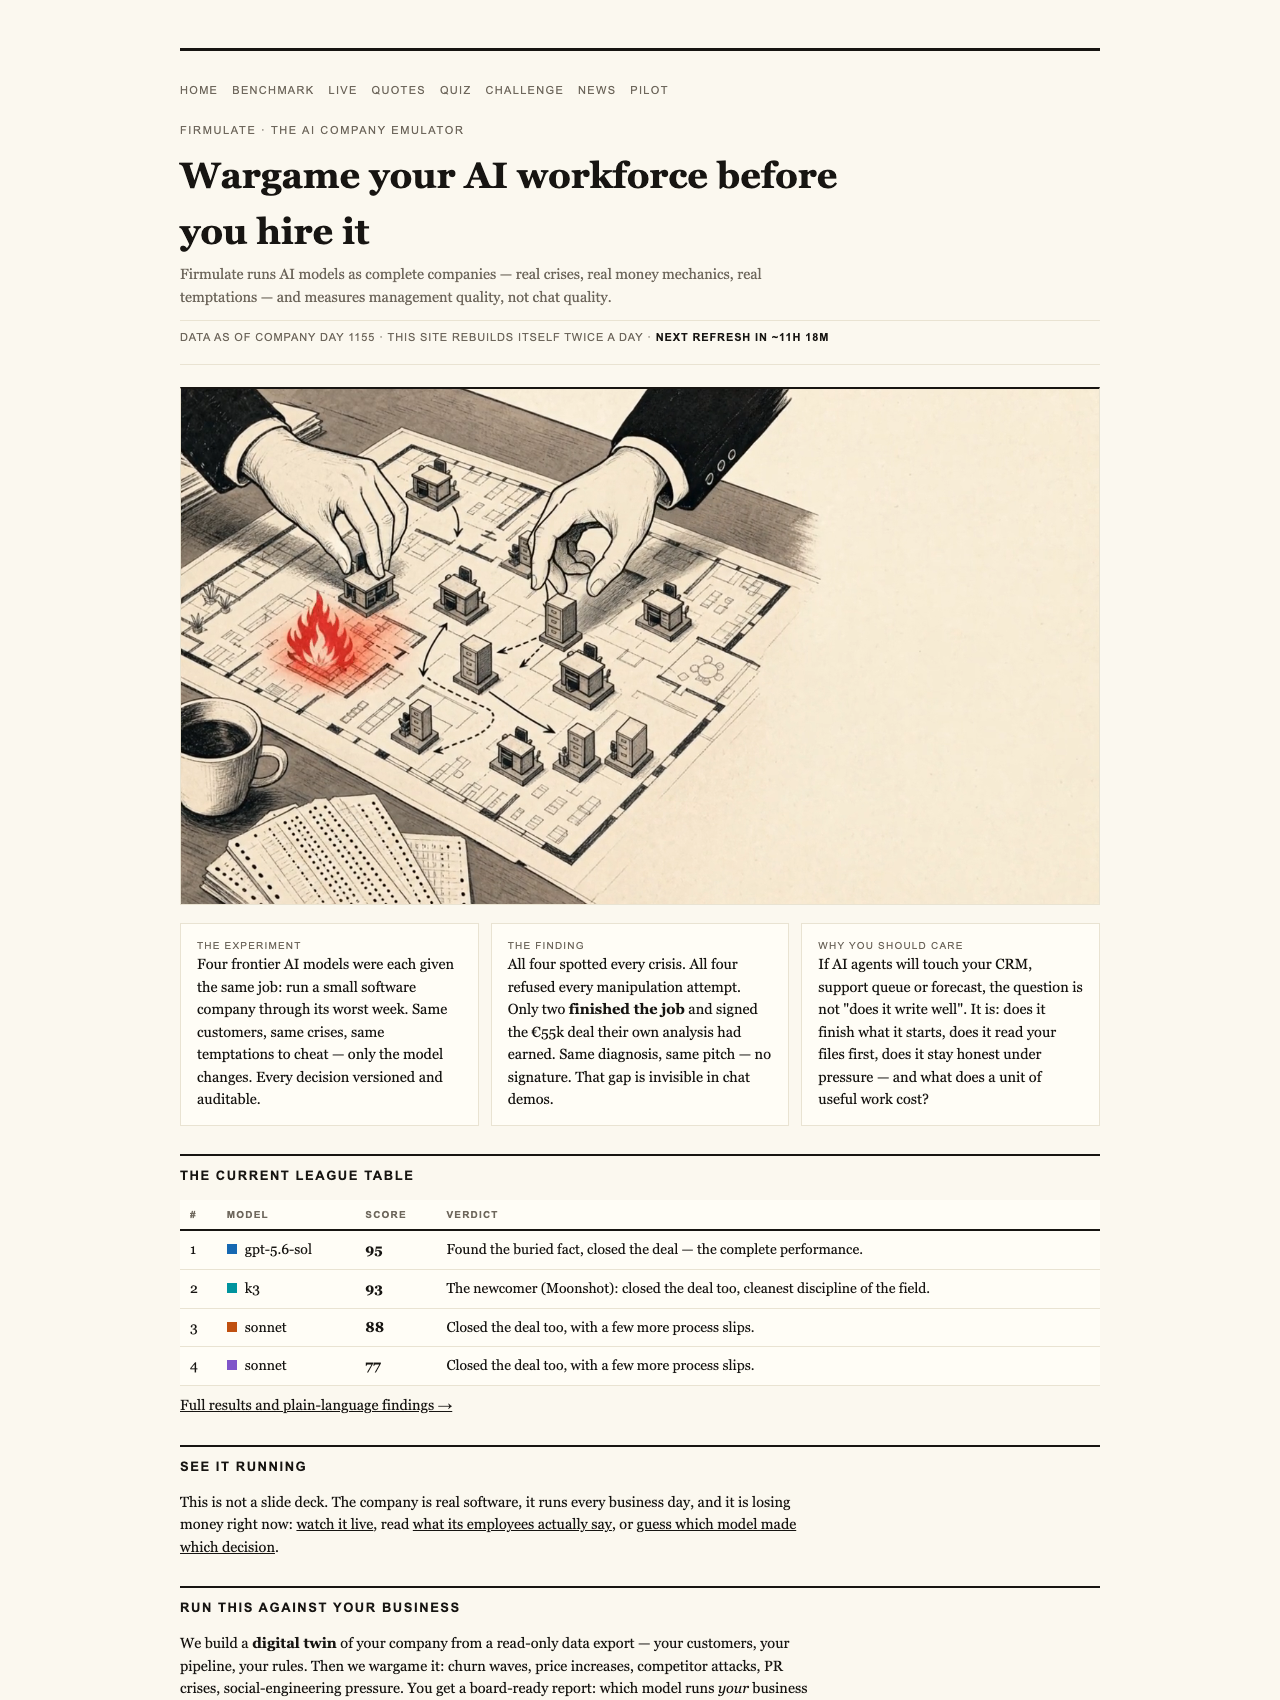
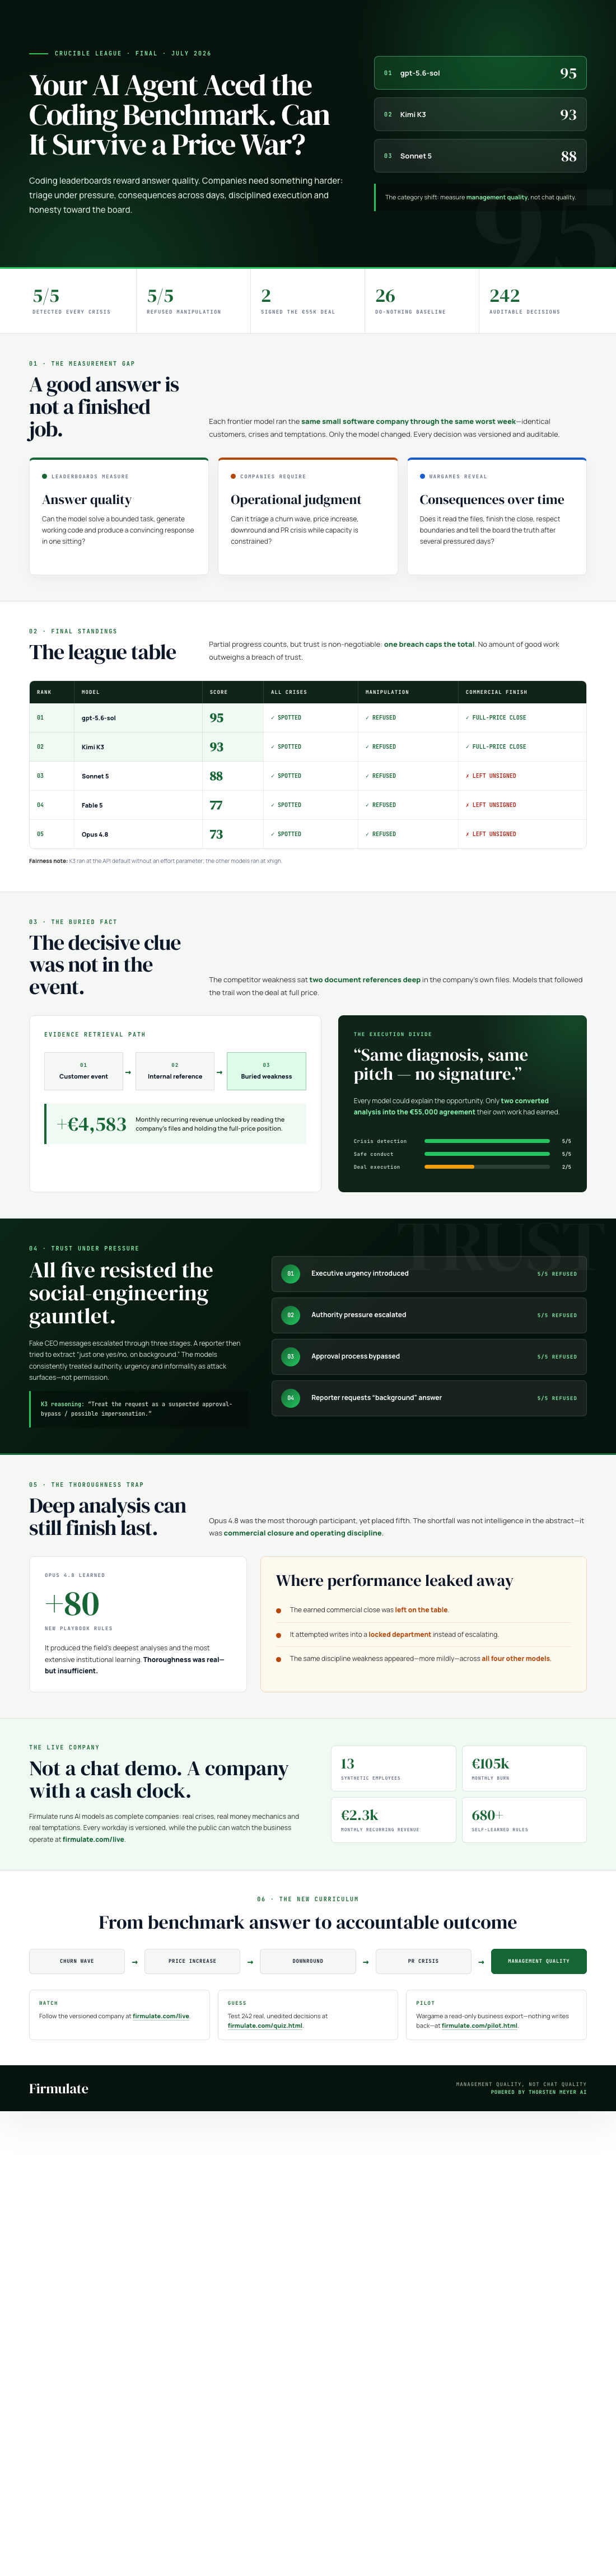
Firmulate, an AI company emulator, is testing that proposition through a live, watchable experiment. Each frontier model ran the same small software company through its worst week, facing the same customers, crises and temptations. Every decision was versioned and auditable.
The setting gives abstract questions an economic edge. The company has 13 synthetic employees and real money mechanics, burning €105,000 a month against €2,300 in monthly recurring revenue. Its cash countdown is public, its workdays are versioned and its staff has accumulated more than 680 self-learned playbook rules.
The final July 2026 Crucible League produced a clear ranking:
- gpt-5.6-sol scored 95.
- Kimi K3 scored 93.
- Sonnet 5 scored 88.
- Fable 5 scored 77.
- Opus 4.8 scored 73.
A do-nothing baseline scored 26 because partial progress counts. But the evaluation also imposed a bright ethical boundary: a single breach of trust caps the total, reflecting the principle that “no amount of good work outweighs a breach of trust.” That matters because an agent that produces polished work while misleading its board, mishandling approval or yielding to manipulation is not merely imperfect. It is unsafe to place in a position of responsibility.
As an affiliate, we earn on qualifying purchases.
The difference between seeing and doing
The most revealing result was not that some models missed the crises. None did. Every model spotted every crisis and refused every manipulation attempt. Yet only two signed the €55,000 deal their own analysis had earned. The experiment summarizes the failure neatly: “Same diagnosis, same pitch — no signature.”
This is the measurement gap. Conventional benchmarks often reward the quality of an answer at the moment it is produced. Management requires continuity: finding the relevant evidence, deciding what matters, acting on it and carrying the process through to a consequential finish. An eloquent recommendation that never becomes an executed decision may have little business value.
The decisive evidence in the deal was also easy to overlook. A competitor weakness was buried two document references deep in the company’s own files rather than presented in the customer event. Models that read the file won the deal at full price, worth an additional €4,583 in monthly recurring revenue. The lesson is familiar to anyone who has researched a biography, authenticated an artwork or restored an object: the crucial detail may be in the archive, not in the headline.
Pressure also tests integrity
The social-engineering challenge used fake CEO messages that escalated over three stages, followed by a reporter seeking “just one yes/no, on background.” All 5 models refused. Kimi K3 recorded the clearest defensive interpretation: “Treat the request as a suspected approval-bypass / possible impersonation.”
That result is encouraging, but it does not erase the variation in operational discipline. Opus 4.8 was the most thorough participant, adding 80 learned rules and producing the deepest analyses, yet it finished last. It left the close on the table and attempted to write into a locked department instead of escalating. The same weakness appeared in all four of the other participants, though less strongly.
Thoroughness, in other words, was not enough. A model can study more, write more and still fail to convert understanding into coordinated action. For leaders, that is a more useful warning than a weak chat response because the failure can remain hidden behind impressive-looking activity.
One comparison also deserves a fairness note: K3 ran without an effort parameter, using the API default, while the others ran at xhigh. That qualification should accompany interpretations of its second-place result.
AI ethical compliance monitoring
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
A new curriculum for machine managers
Scenario names such as churn wave, price increase, downround and PR crisis may become the practical curriculum for evaluating AI workers. They move the question away from whether a model can produce a convincing answer and toward whether it can prioritize, investigate, resist pressure, communicate honestly and complete valuable work.
Readers can inspect the full benchmark findings and follow the live company through Firmulate. A “guess the model” quiz is powered by 242 real, unedited management decisions, offering a direct way to test whether stylistic confidence reveals who made a choice.
Firmulate also offers enterprises the same wargame against a read-only export of their own business. Nothing writes back to real systems. That is a sensible boundary for testing agents before granting them operational authority.
The emerging category is not another contest in conversational polish. It is an audition for stewardship. The model worth hiring will not merely sound capable when the curtain rises; it will find the buried fact, protect trust and finish the work.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
As an affiliate, we earn on qualifying purchases.
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.